


This is a guest post written by Ashley Ferro, a freelance content writer & copywriter specializing in SEO content marketing.
File naming conventions are shared rules for structuring filenames so people and systems can identify, sort, search, and manage documents consistently. A useful convention defines which information belongs in a name, the order of each element, allowed separators, and how versions are recorded.
It is all too common to find yourself wading through your organization’s shared folders in search of the file you have been asked to review:
- PROJECT-PROPOSAL-NEW-v5.doc
- Project_proposal_2020_final+edits.doc
- THIS_is_the_final_proposal_(old-version).PDF
Why does this happen? Common causes include the lack of a clear internal policy or procedure, weak folder architecture, and inconsistent habits. The result is document spaghetti: duplicate files, uncertain versions, and wasted time.
With a small amount of effort, you can create names that make the correct document obvious before anyone opens it. The more organized your internal information becomes, the easier it is to work efficiently and trust the record in front of you.
This guide covers:
- File naming conventions: Best practices and tips
- The Dewey Decimal file naming convention
- Process standardization vs process harmonization
- How Process Street organizes process knowledge
- How to organize a process library
- File naming convention FAQs
File naming conventions: Best practices & tips
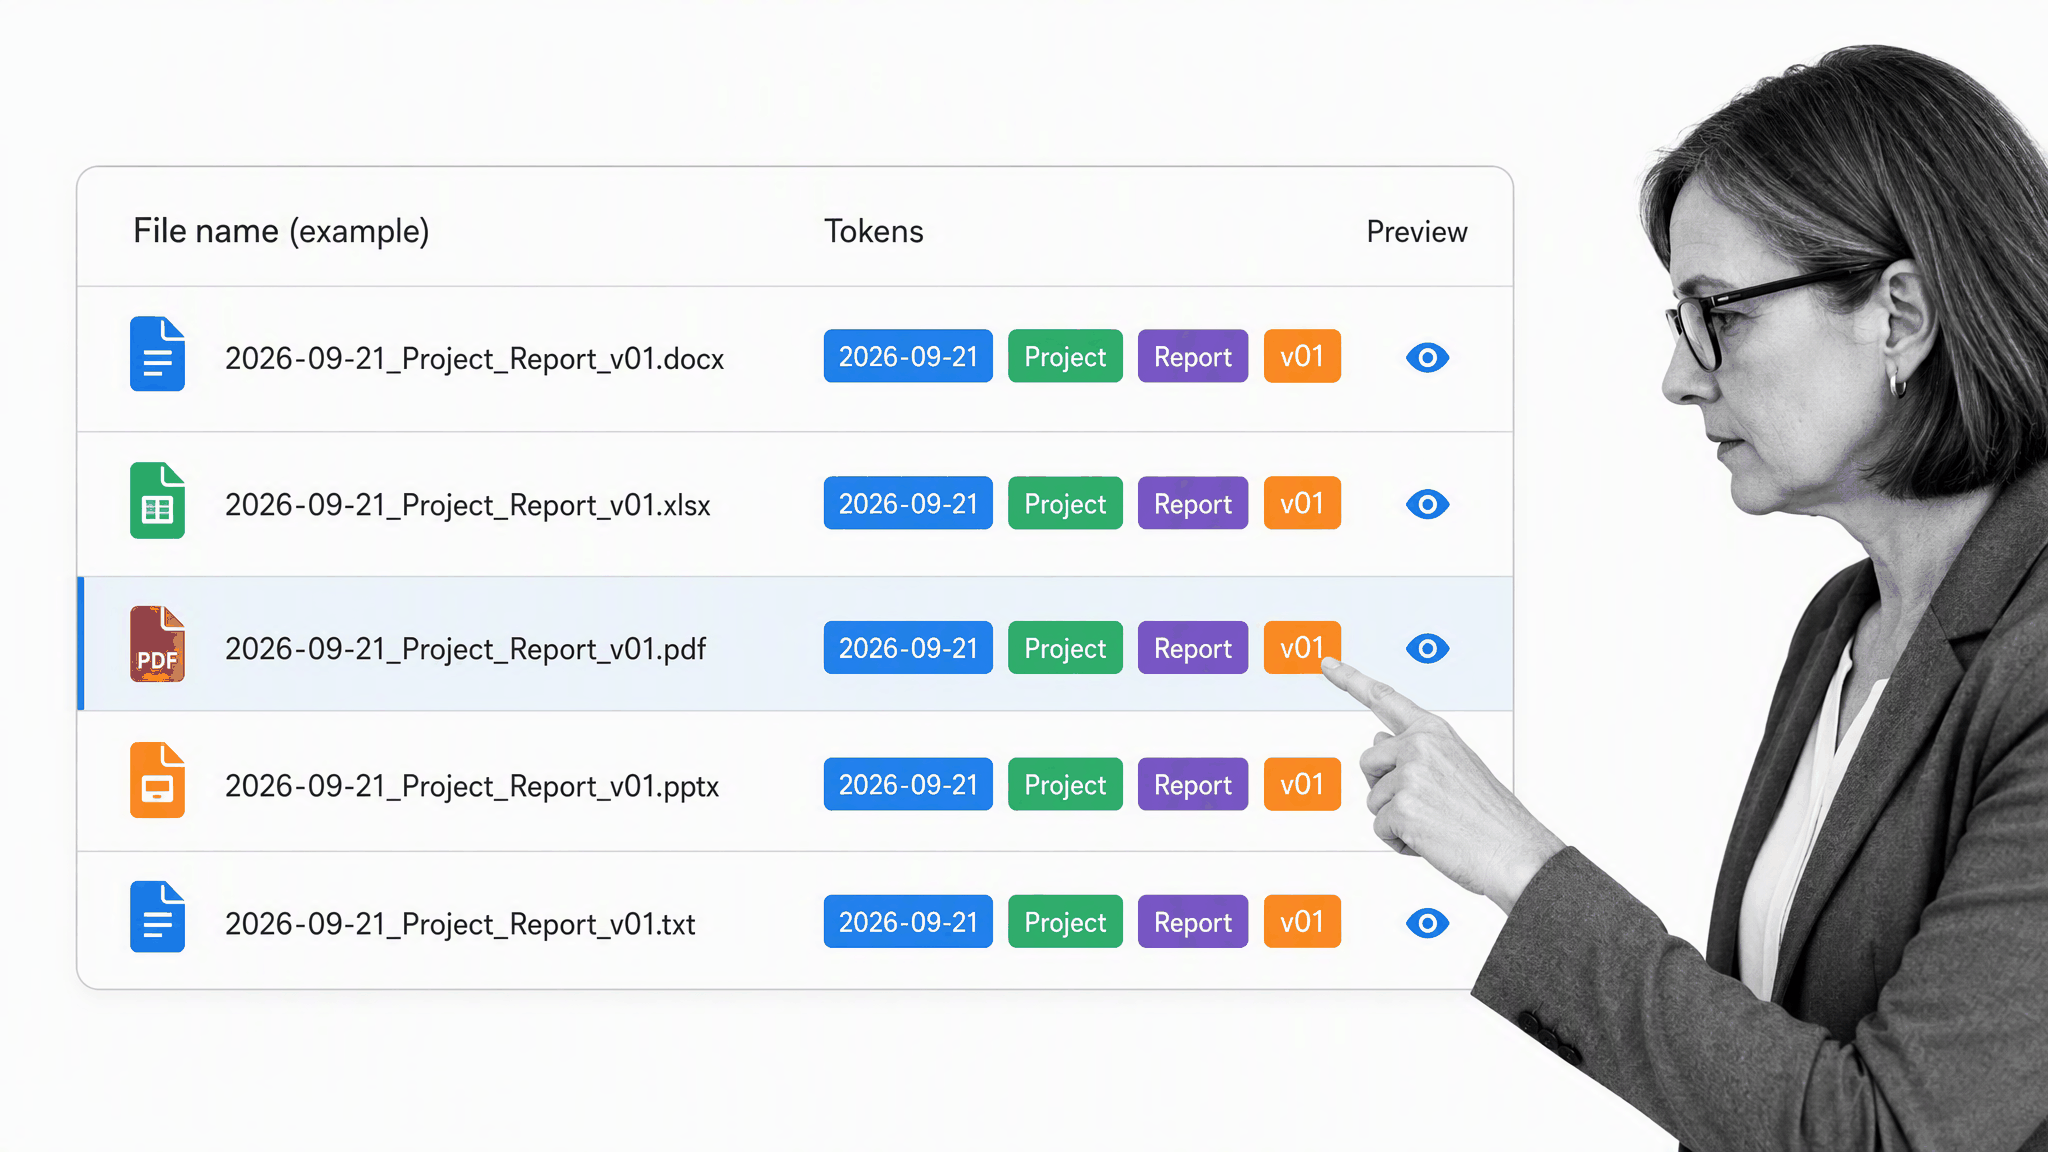
This section will consider some best practice conventions for file naming. Whether you’re a small organization or a large enterprise corporation, these principles should be relevant, because they’re designed to consider the needs and requirements of each case before administering any one solution.
- Establish your information architecture
- Readability: Humans vs Robots
- Wikipedia shows that being digital can broaden your categorization
Establish your information architecture
“Information architecture” is the way you organize your internal information, in terms of how you design the system that allows you to access and manage that information.
Websites are a great, pragmatic example of informational architecture – they’re quite literally formal systems of information organized into a navigable and interactable interface. Hyperlinks, site maps, and navbars all represent the architecture (the links between different pieces of information) of the websites you’re viewing.
Of course, we’re not necessarily talking about websites. Information architecture is a broad concept that can be applied to any kind of knowledge management. In any case, building solid information architecture will depend on a deep understanding of what information you have, and the most efficient and effective way to make sense of all of that.
What does “efficiency” or “effectiveness” mean for information management? You can start by considering who will need to access the information. Will there be multiple iterations of similar files, many files across different areas of the organization, multiple departments accessing the same area? This kind of thing.
Efficiency can be understood as the shortest time possible taken to access any given file. How many clicks is also a relevant metric. Is the folder structure unnecessarily complex, taking 10 clicks through empty category folders before reaching the destination file? Consider if more horizontal organization is a better option, with a couple of clicks to relevant files.
Effectiveness can be understood as whether or not the file naming conventions help or hinder the completion of daily tasks. How many different files do you have to open before you find what you’re looking for? Is the file naming convention intuitive, or do you need to spend extra time learning how to make sense of 010220_MA_P-01_Project_1_Draft.doc, when Marketing_Project_Proposal_June_v1.doc would do just fine?
Readability: Humans vs Robots
One of the most important questions you can ask is: Who are you organizing your files for? All said and done, who will actually be using this system of file naming conventions to navigate your library?
It may be that you’re organizing internal media files in a remote organization, or for a local intranet – in that case, you probably want the files to be human-readable. In that case, something like this might make sense:
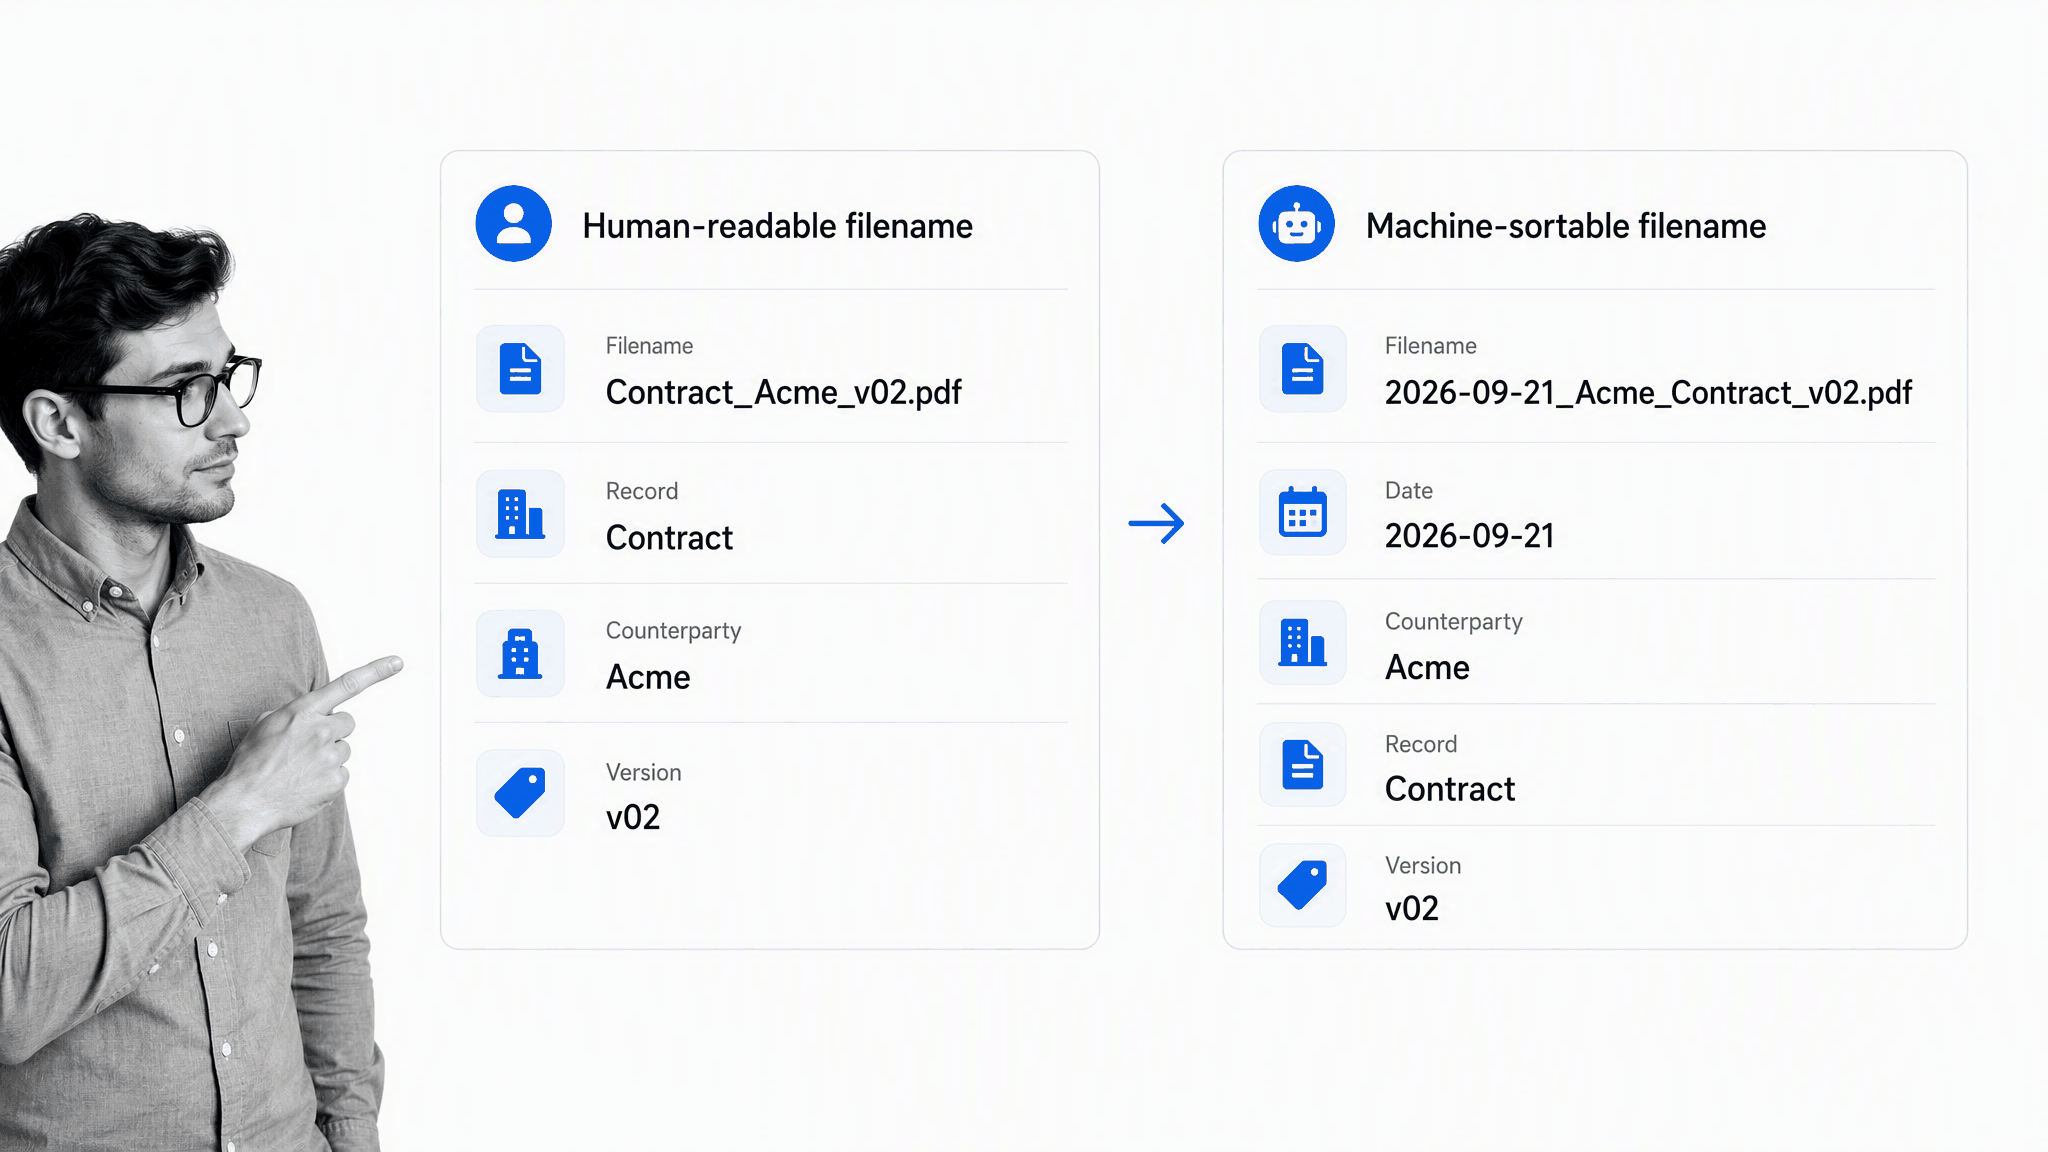
Keeping things short, meaningful, and removing unnecessary information will help people navigate your files with minimal effort.
On the other hand, perhaps you’re tasked with managing large batch files for automatic processing or robotic search, in which case, human readability might not be your primary concern (though it’s probably still useful, in the least for debugging and error-chasing purposes.)
Design names for browsing, search, and automation
Wikipedia demonstrates a useful information architecture principle: people need more than one route to the same record. They can browse categories, follow links, or search directly. A document library should support the same behavior.
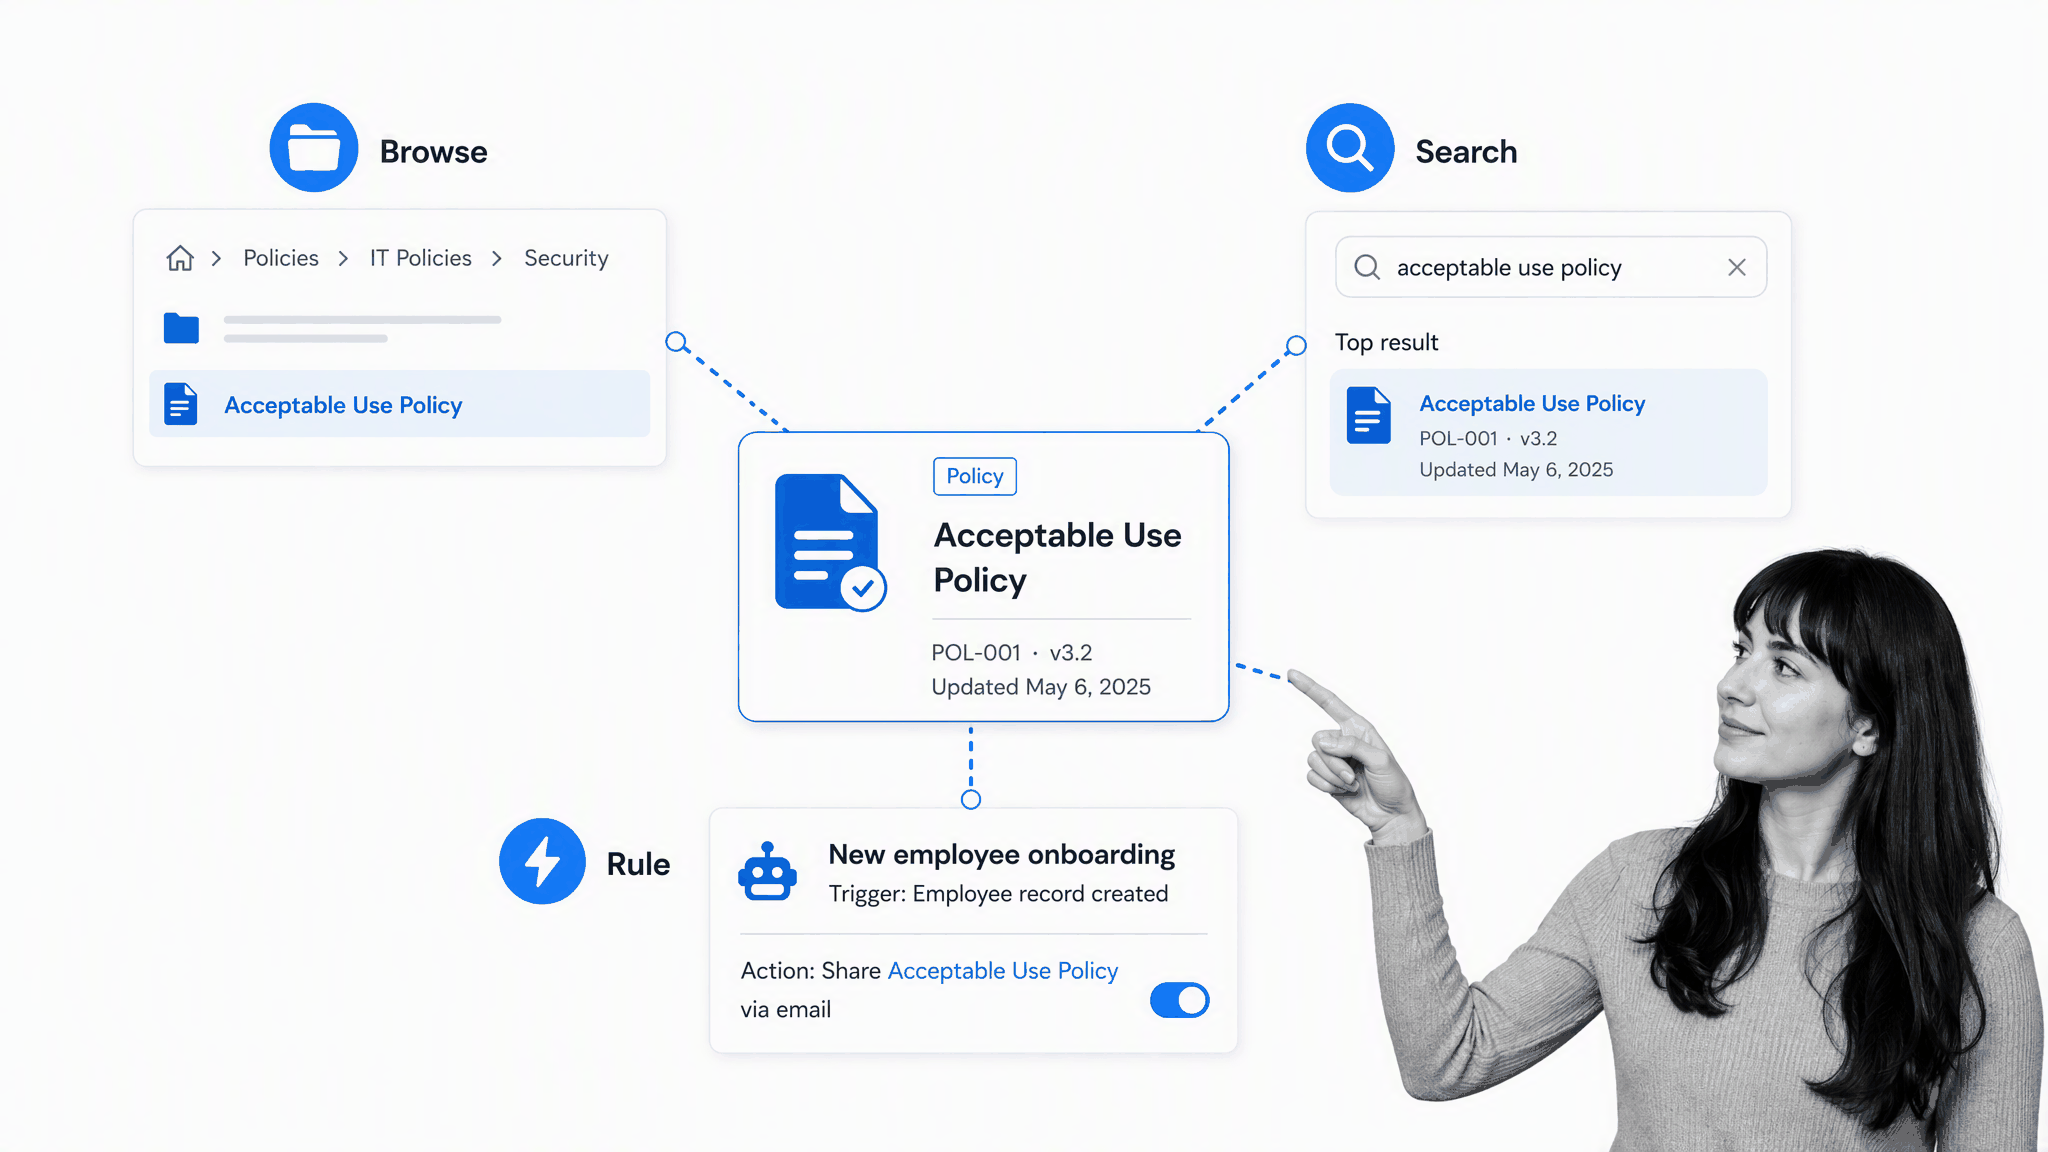
A predictable filename creates searchable metadata even when a document is copied outside its original folder. A practical pattern is {YYYY-MM-DD}_{project-or-client}_{document-type}_{v##}.{ext}, for example 2026-09-21_Acme_Contract_v02.pdf.
- Use ISO-style dates:
YYYY-MM-DDsorts chronologically and avoids regional ambiguity. - Choose one separator: underscores or hyphens are safer than spaces across common systems.
- Use leading zeros: write
v01,v02, andv10so lexical sorting stays useful. - Keep the vocabulary controlled: agree on document types such as
Contract,Invoice, orPolicy. - Avoid restricted characters: Microsoft documents characters and filename limitations for OneDrive and SharePoint.
The goal is not to pack every detail into a filename. Use the smallest set of stable fields that helps people recognize a file and helps systems sort or route it. Store richer metadata in the document management system.
The Dewey Decimal file naming convention
“Dewey Decimal” refers to a file naming convention named after a 19th century American librarian named Melvil Dewey. Originally, it was a method of organizing information (books) based on 10 main classes that attempted to cover… well, pretty much everything.
Who’s it for & what problem does it solve?
We should remember that the Dewey Decimal Classification (DDC) was first and foremost a system designed to be used in libraries. It was also originally designed to be organized by discipline, as opposed to topic. This has changed over the years, and many places, libraries and other such organizations, implement their own flavor of Dewey Decimal.
The Dewey Decimal Classification remains a widely used library classification system. OCLC reports use in more than 135 countries. So what can we learn from this naming convention?
The main problem Dewey Decimal solves is organizational. It helps arrange books in a way that allows anyone browsing to swiftly find what they’re looking for. For better or worse, the Dewey Decimal system is here to stay, and its longstanding legacy speaks to its efficacy as a file naming convention.
How does it work?
The best way to explain how the Dewey Decimal system works is by showing. Here’s a table organized using Dewey Decimal:
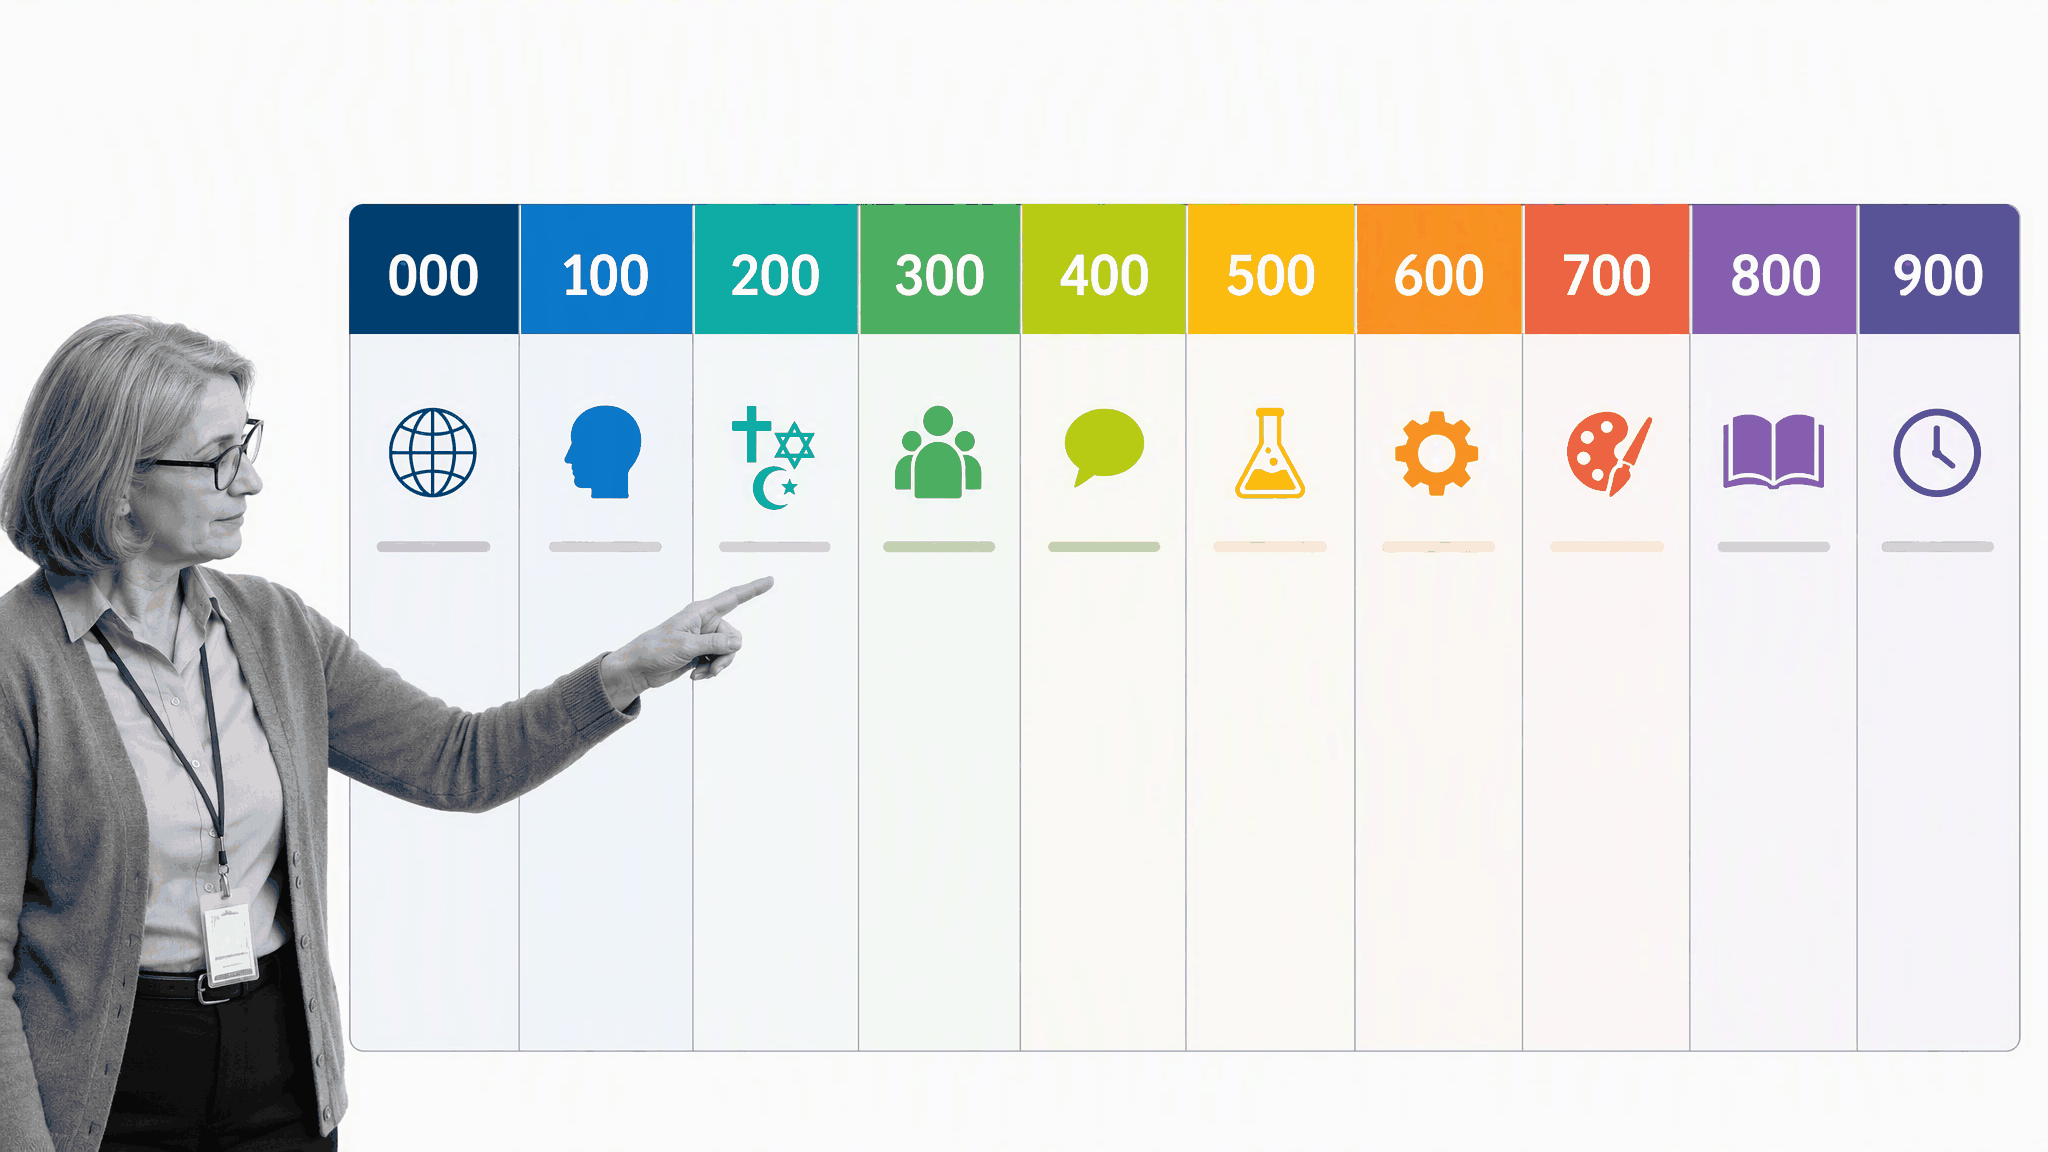
Notice on the left hand side, there are numbers from 000 to 999. This is the “decimal” element. Here we have:
- 10 main classes
- 100 divisions
- 1,000 sections in total
Essentially, the system uses numbers to divide broad classes into smaller, more specific divisions and sections. OCLC publishes a summary of the classes, divisions, and sections.
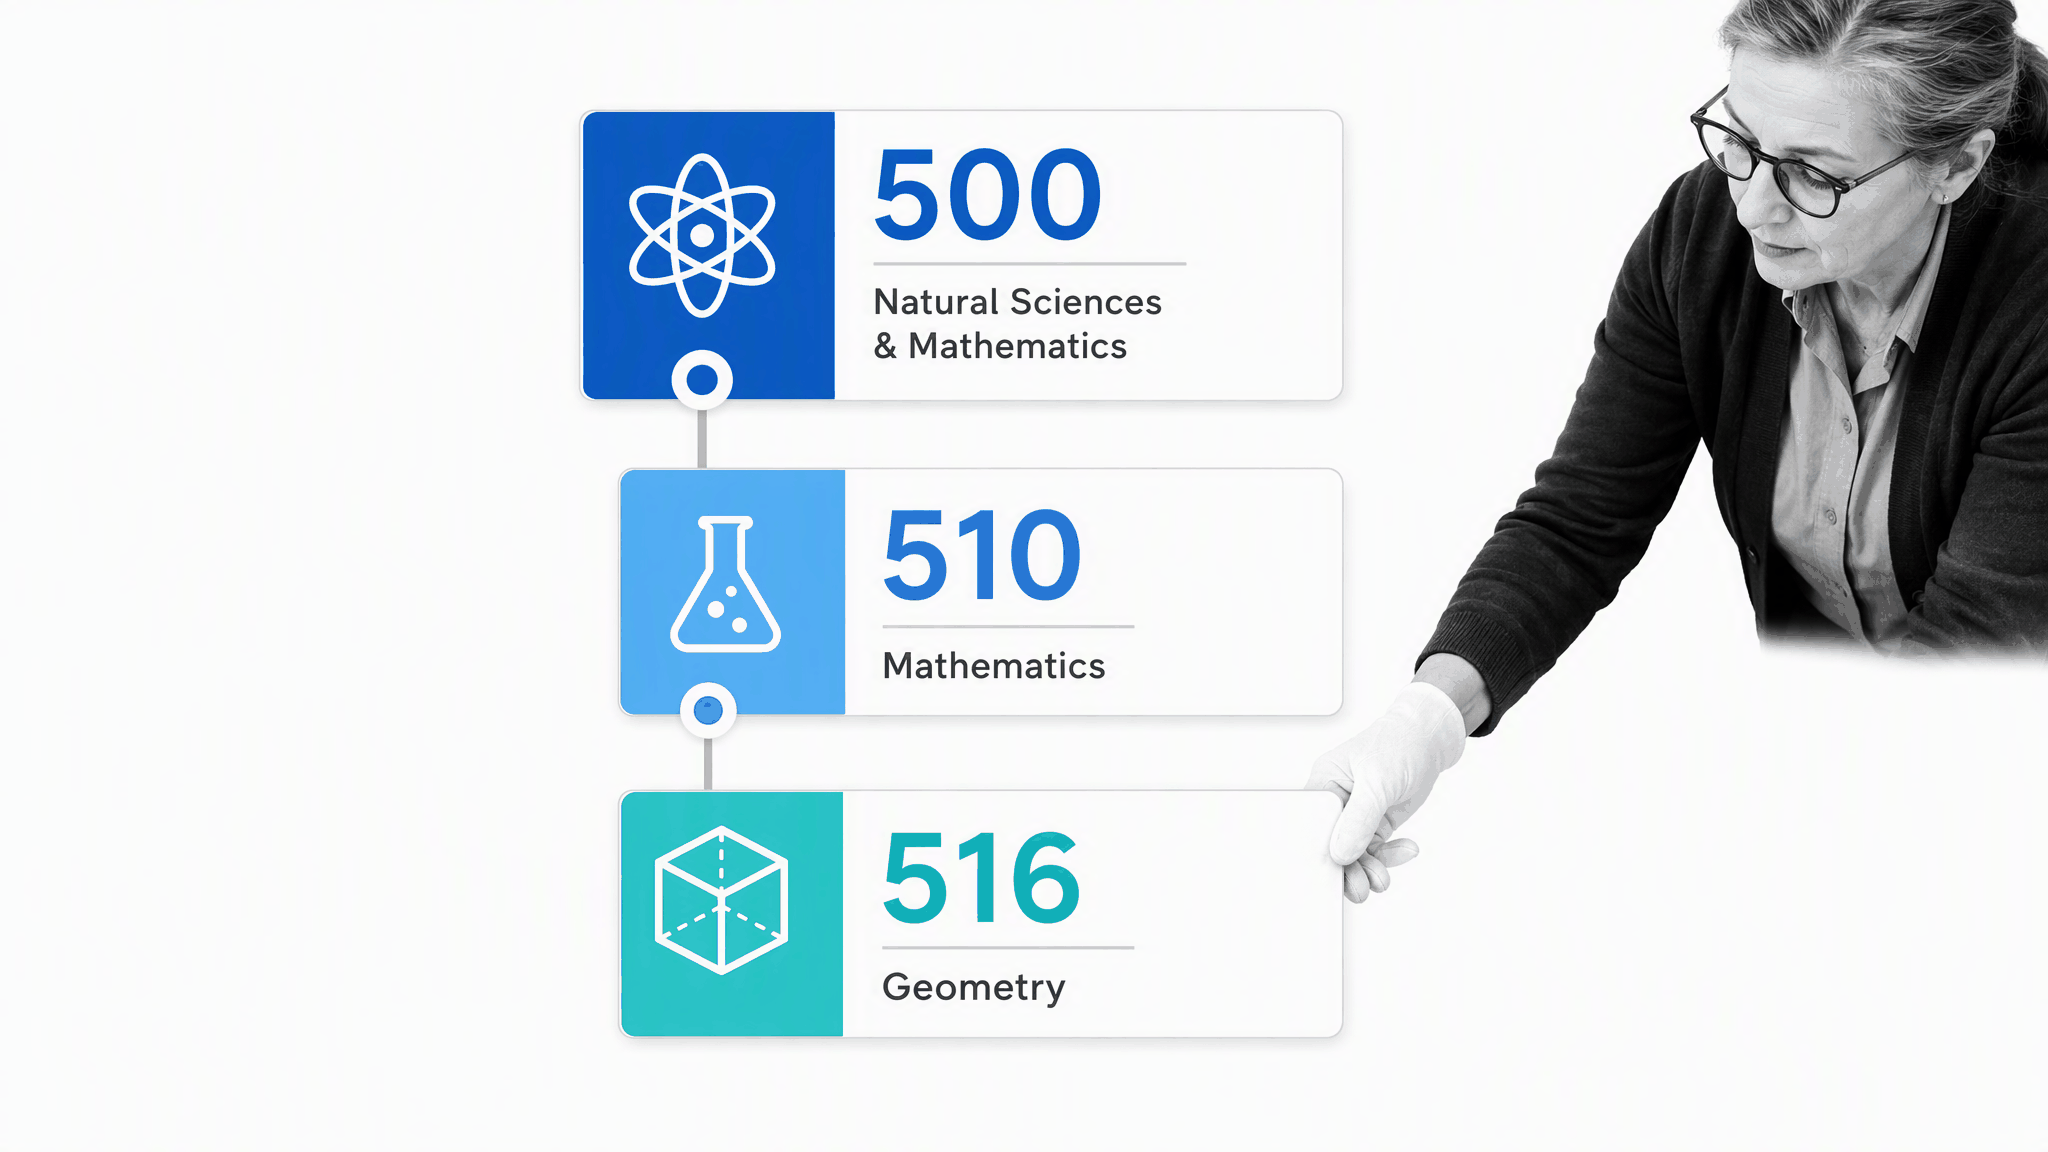
Strictly speaking, you could take these sections and further subdivide with actual decimal points (many larger libraries do) like so:
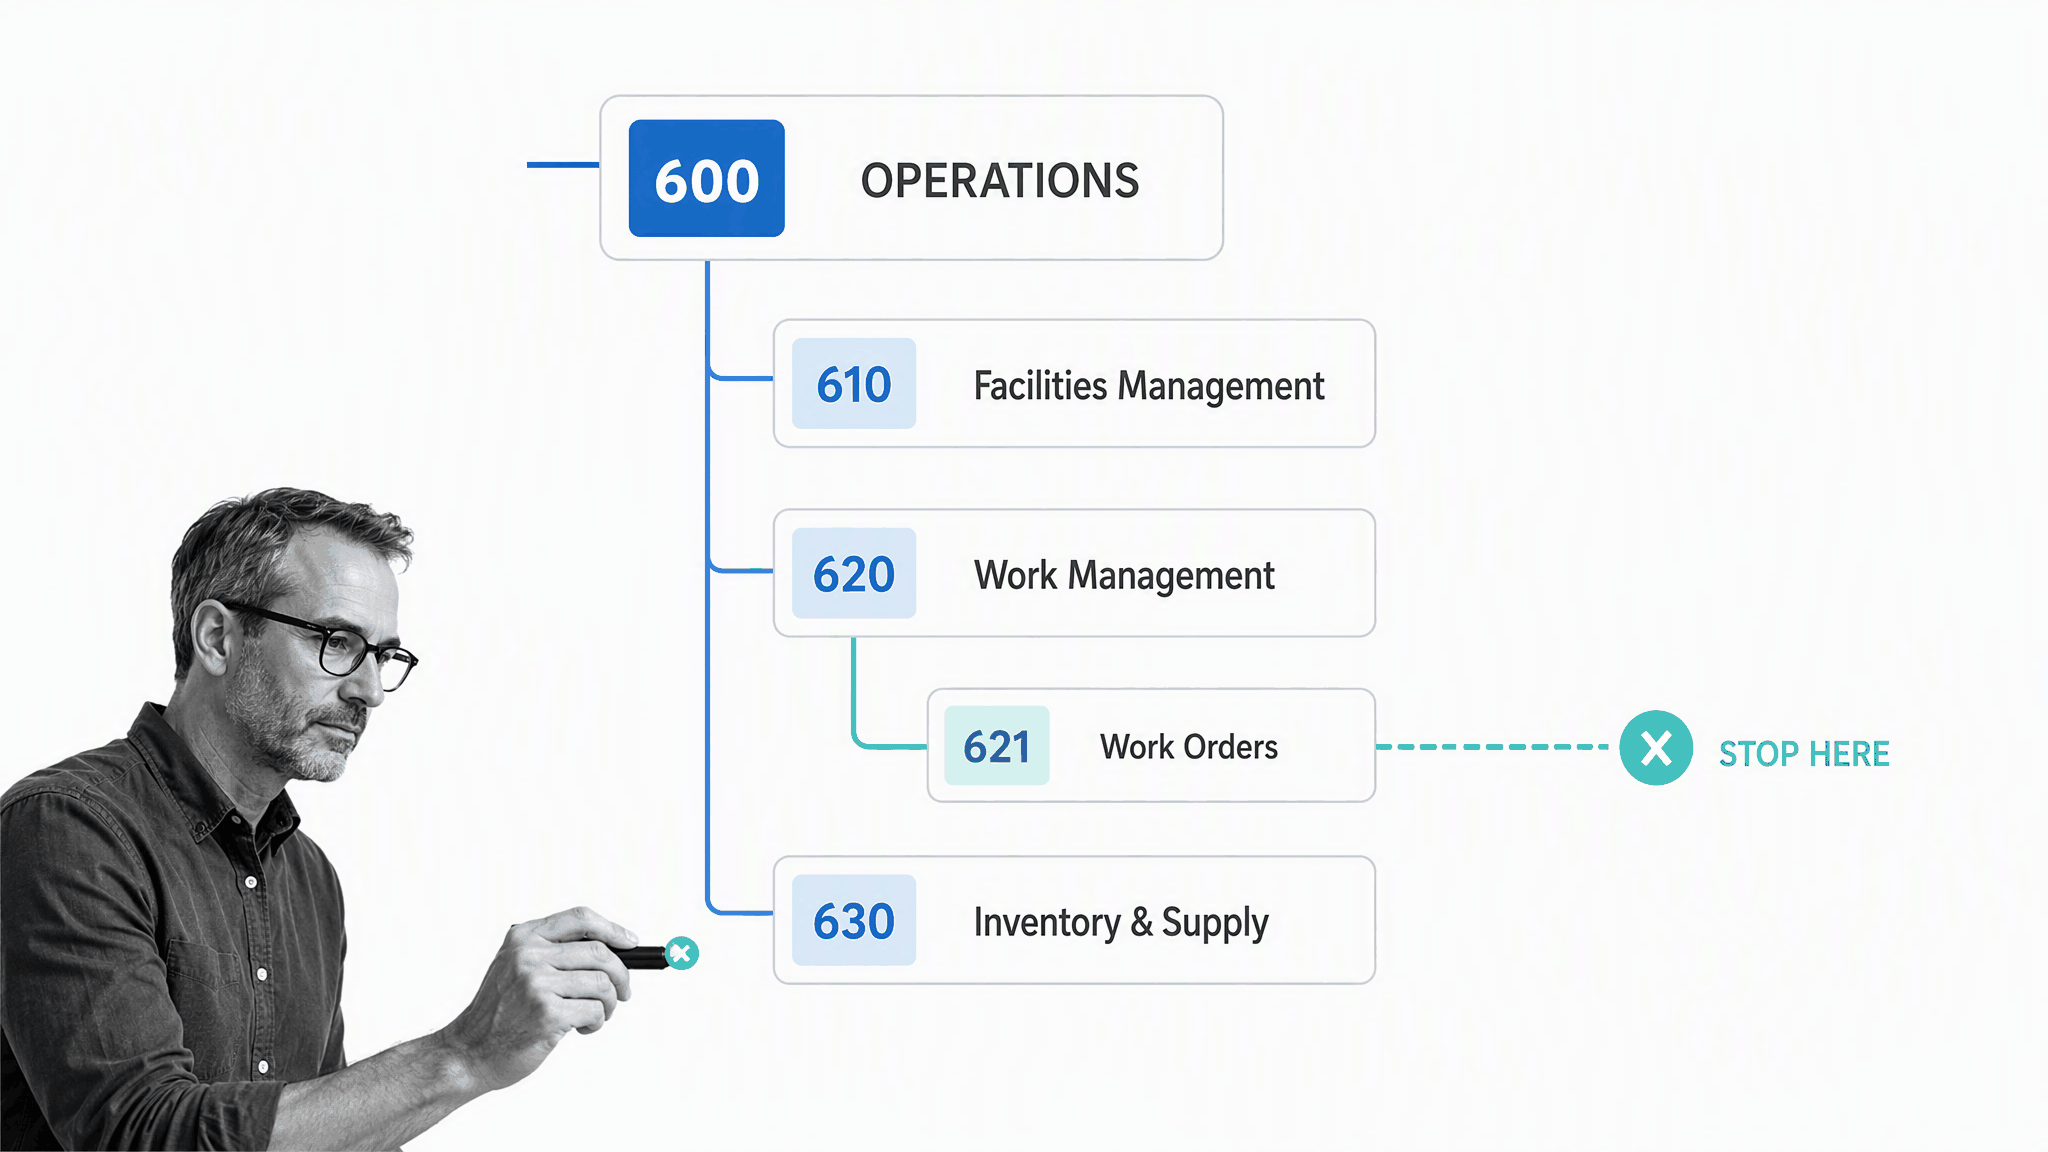
However, you should determine whether this is necessary or simply overkill, depending on your internal file and process library.
Adapting Dewey Decimal for your organization
One of the pitfalls of the original Dewey Decimal Classification as a library naming convention is the fact that it tends to reflect any biases in its organizational structure.
This is more a problem when the goal is objective organizational clarity, for example when deciding where certain poorly understood or novel subjects or areas of study should fall on a library shelf. It’s less of a problem when you just want to organize a set of files or processes for your internal organization.
In fact, bias can actually be helpful here. Different teams in an organization will have different biases towards organizational structure, including how core files and procedure documents are stored.
For example, the bias of the engineering team might be useful when deciding how the files and/or processes for that team should be organized.
Who better to manage and own the organization of forms, files, and recurring processes than the people who use them most?
You might not need a thousand-manifold Dewey Decimal structure to organize your internal files and processes. But you might be able to use the principles of DDC to improve your file naming conventions. If you can implement a simple, intuitive structure with numbered subdivisions of specific categories and functions, you’re one step closer to improving the searchability (and therefore the utility and actionability) of your internal file structure.
Process standardization vs process harmonization
Small businesses are in a great position to implement really solid file naming conventions and standardize their processes. When you focus on solving these problems early, before you grow and expand too large, you solve a simple problem before it grows wildly unmanageable.
As a SMB, you don’t have so many internal processes, so it’s easier to manage them all and get to the point where you have everything under control.
If you run a small business, you don’t need five different documented processes for storing documents or dealing with different projects and clients. Even if you manage two or three similar establishments like this, it’s easy to be sure that all of these use the same methods.
The challenge you face will come when you reach the point of having 1,000 different establishments in different countries, that need to follow different laws and regulations, or sell different products or services. This becomes a question of process standardization vs process harmonization.
Process standardization means making one process for one job and keeping it the same, no matter where you use it. Obviously, this won’t work if you need to work across different countries or navigate different regulations. Process harmonization, then, is about setting a standardized core, but allowing for subtle changes as and when to accommodate for different use cases and scenarios.
Standardization or Harmonization? You need Both is a paper by Albrecht Richen and Ansgar Steinhorst that delves into the relationship between these two terms.
What’s the point here? Companies should take process standardization more seriously, but they should also understand the difference and value between standardization and process harmonization.
Three recurring challenges appear when organizations standardize work:
- Processes for the sake of processes: too many processes for things that really don’t need processes, meaning wasted time and resources.
- Over-standardization: to the point where processes become so rigid and inflexible that they are rendered ineffective.
- Resistance to changing processes: Even if your goal is standardization, you should give employees space to attempt to make changes to and improve processes.
How can we apply these insights to the problem of file naming conventions, and more broadly, overcoming the challenges of information architecture?
Three practical responses are:
- Build and maintain a process library – staff should have a central repository of all internal processes and procedures, with a clear file naming convention and informational structure. Once this is established as a clear initiative, it helps to establish an internal culture more observant of proper file naming conventions and knowledge management.
- Optimize your processes – either via standardization or harmonization. How you approach this practically will depend on your company. In any case, your goal is to improve the efficiency and effectiveness of your processes.
- Implement top-down changes – this helps establish clear best practices for knowledge management and will also help to build a more effective company culture around best practices. Consider establishing a process-focused team with members from different departments to meet regularly and discuss the best way to optimize processes in their respective teams. This approach helps facilitate both standardization and improvement.
How Process Street organizes process knowledge
File naming conventions work best when they sit inside a governed system for creating, approving, using, and retiring process knowledge. Process Street is a single Compliance Operations Platform with Docs and Ops capability areas plus built-in AI.
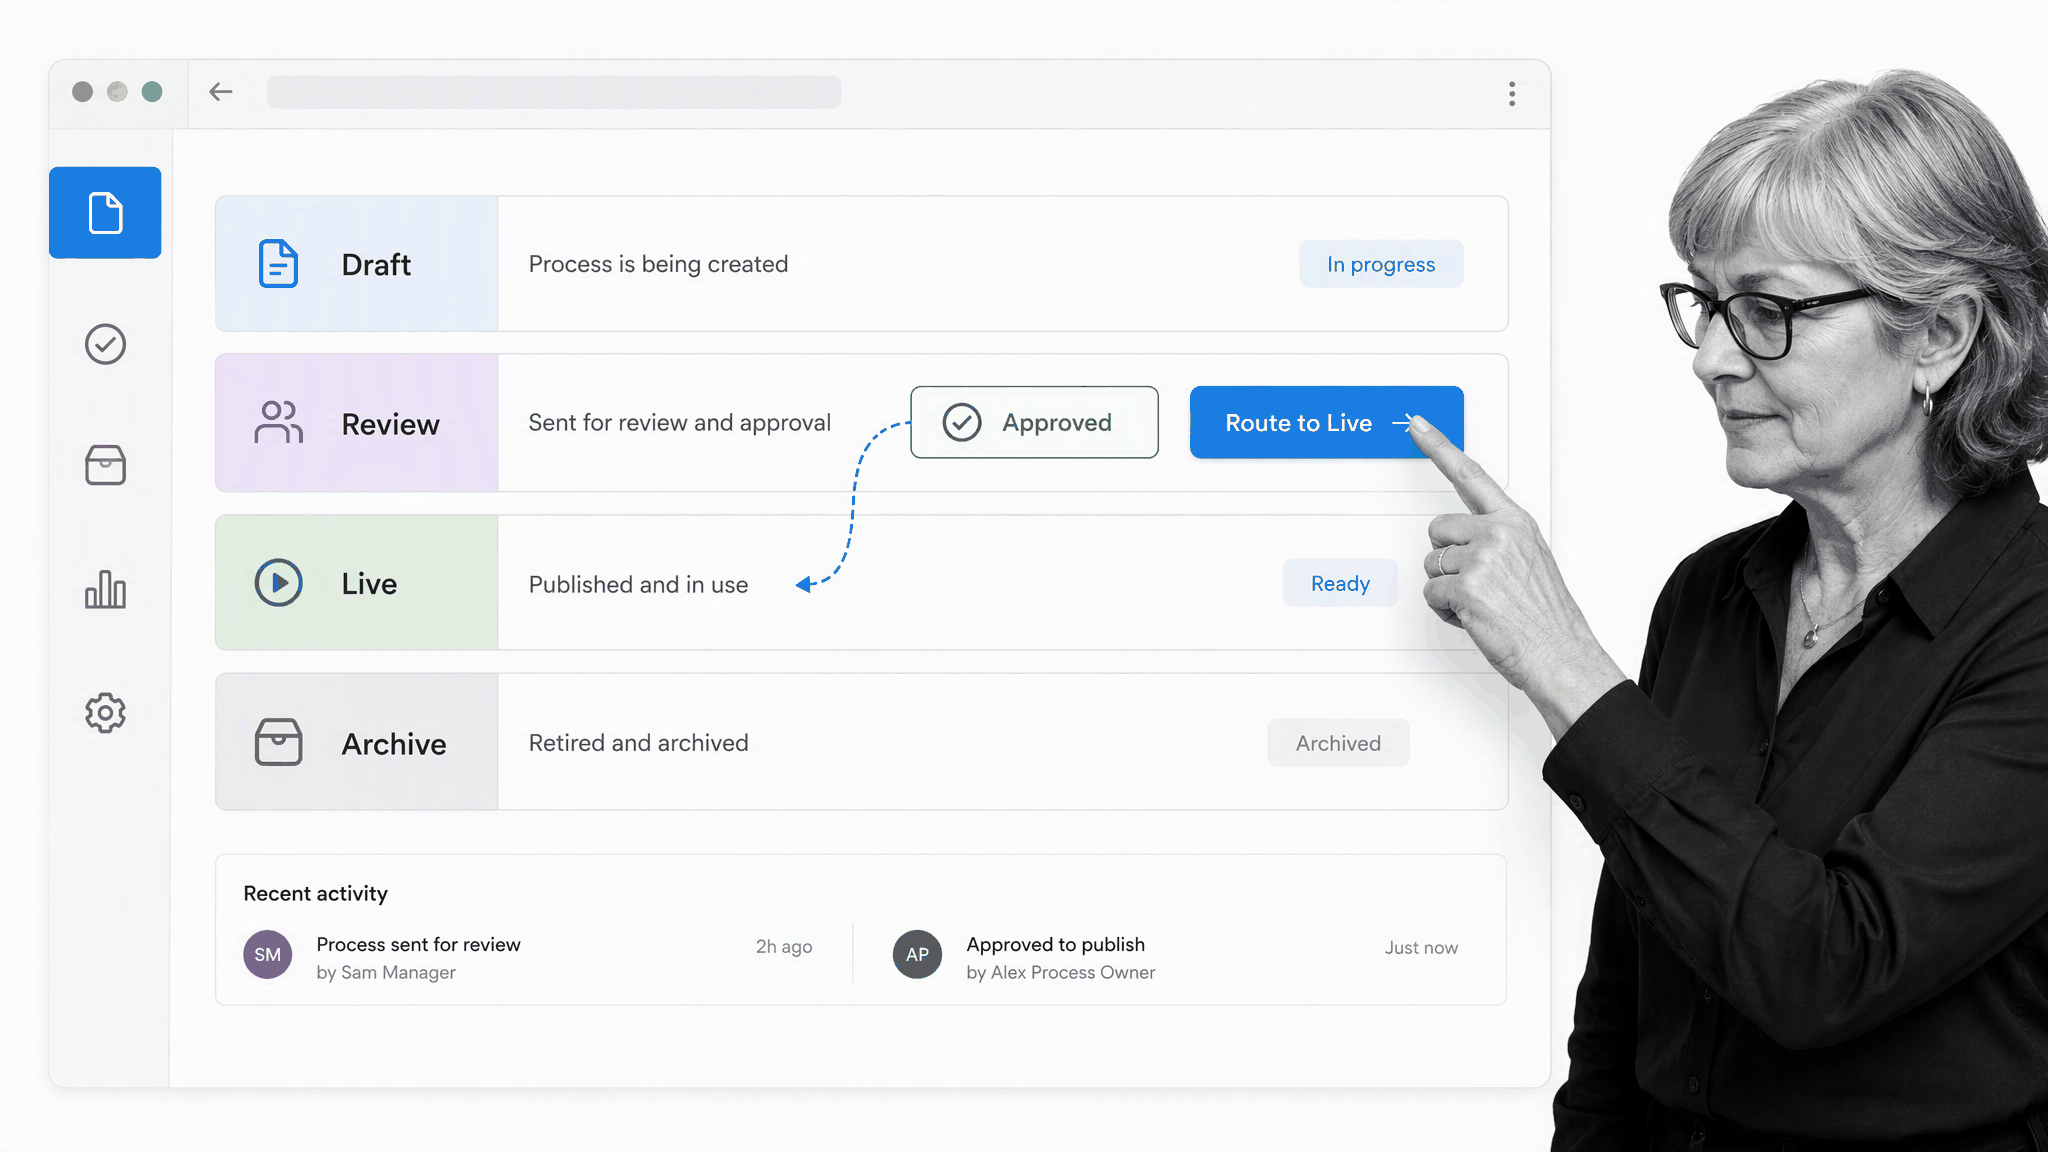
- Draft: Process owners create or update instructions, forms, and supporting documents.
- Review: Subject-matter experts and control owners check accuracy, ownership, and required evidence.
- Live: Approved procedures are available for teams to run consistently in Ops.
- Archive: Retired material remains governed without cluttering the active process library.
Docs gives teams a controlled place for process documentation. Ops turns that knowledge into assigned workflows with forms, approvals, due dates, and an activity record. Built-in AI helps teams create, operate, and improve processes inside the same product. Clear names still matter because exported records, attachments, and supporting evidence need to stay recognizable wherever they travel.
Design the solution around the people who use it. A simple, consistent structure is often better than an elaborate taxonomy that nobody follows.
How to organize a process library
Whether you are creating a process library from scratch or improving an existing one, start with the work people need to find and run. The same principles that improve filenames also make the entire library easier to govern.
- Inventory the current library. Identify duplicates, unclear owners, unsupported formats, and records that should be archived.
- Define a naming pattern. Choose stable fields, an order, approved separators, a date format, and a version format.
- Assign owners. Every process and document should have someone responsible for its accuracy and review schedule.
- Separate lifecycle states. Keep drafts, material under review, live procedures, and archived records distinct.
- Test retrieval. Ask a new team member to find a record by browsing and by search, then fix the points of confusion.
- Govern changes. Use review dates, approvals, and change records so the library stays trustworthy as the organization evolves.
The Process Library Checklist provides a practical framework for this work:
A well-designed library becomes more useful when it connects documentation with execution. Learn how a document management system supports controlled content, or explore process library software for governed recurring work.
The following customer example shows how a team can put repeatable process knowledge into practice:
File naming convention FAQs
What kind of file naming conventions are you using? Share your experiences or horror stories in the comments below.